Blog
Notes from the lab
Essays, research notes, and updates from the team at Moth Labs.
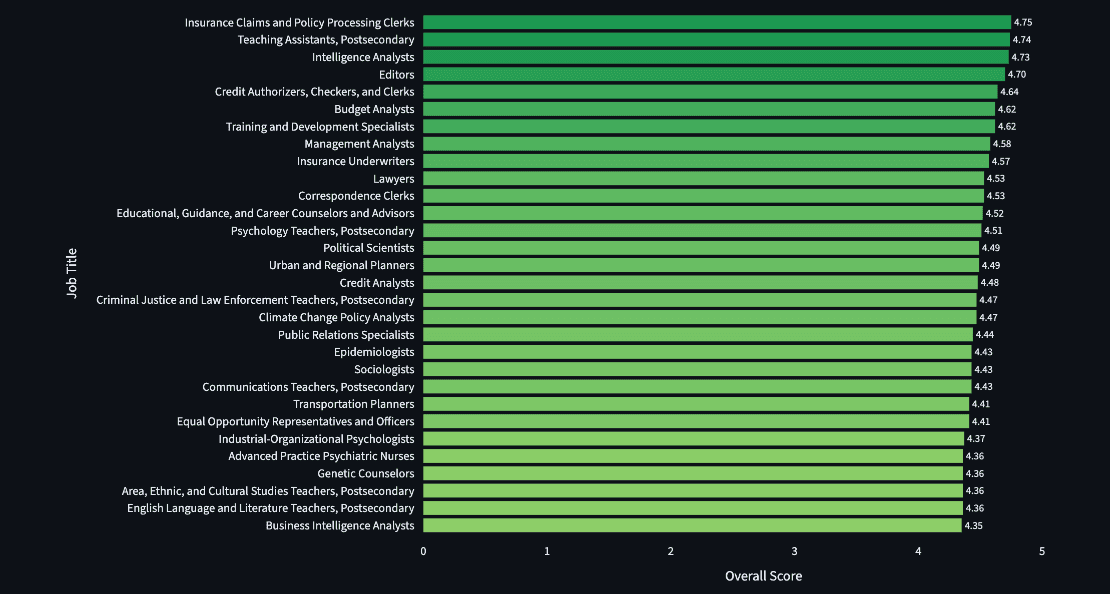
Measuring What AI Can Actually Do: Occupational Exposure Beyond Fluent-but-Flawed Outputs
Current AI occupational exposure indices conflate surface fluency with domain reliability. We introduce the *AI Exposure Evaluation Pipeline* — a teacher–student–judge LLM framework across 114 O\*NET occupations — and identify the *Fluent-but-Flawed* phenomenon: a persistent Clarity–Domain Accuracy gap (mean: 1.55–1.90/5) that constitutes a critical RLHF-induced measurement bias.
Hao Zhang
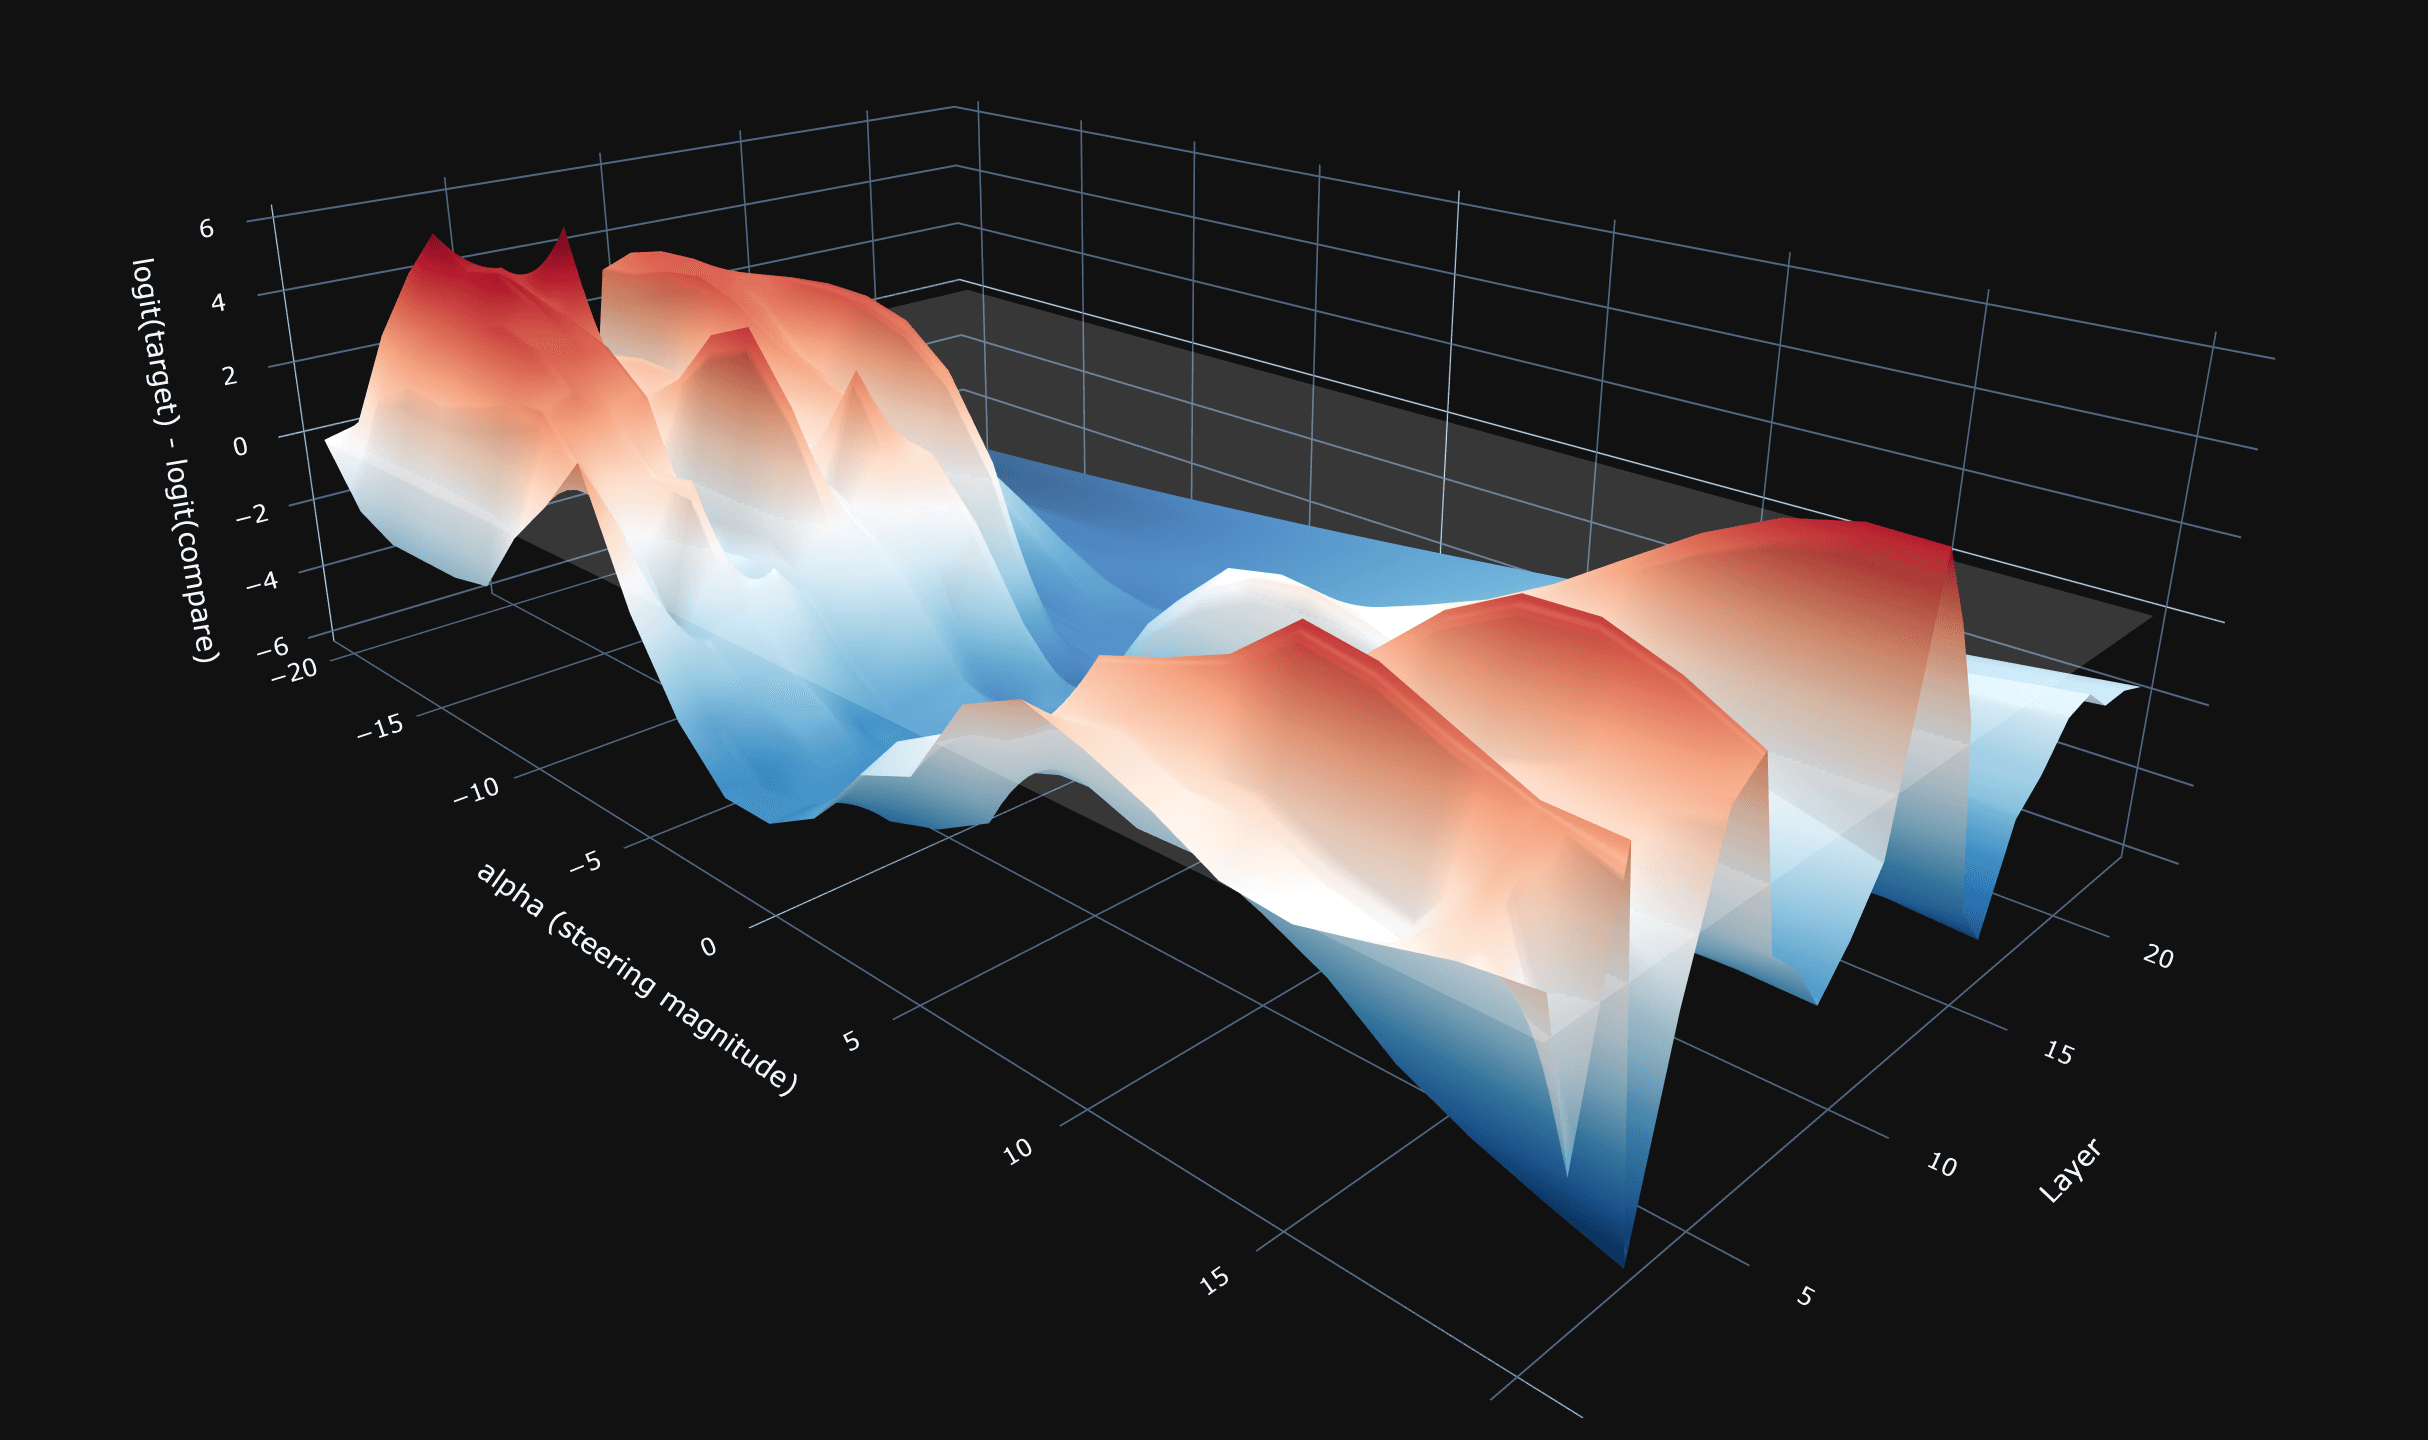
Probing Inside the Black Box with Interpretability Explorer: A Step Toward Practical LLM Interpretability
An open-source mechanistic interpretability tool for exploring model internals through paired prompting. This post walks through a few of the tool’s features and previews an upcoming study on corrigibility.
jack reddick